Most frontend teams think AI testing means prompting an LLM to write Playwright scripts from scratch. That mistake leaves them with flaky suites that fail 43% of the time. The real asymmetric advantage isn't generation—it's self-healing execution that adapts when your UI changes.
The 500-Test Redesign Trap
You spend three weeks building a sleek UI redesign, only to watch your CI pipeline turn bright red. Not because the app is broken, but because 500 end-to-end tests are hunting for CSS classes you just deleted.
This is the exact bottleneck Engagement Agents faced during a major UI overhaul. Instead of shipping, teams normally freeze releases to manually rewrite hundreds of brittle scripts. By using AI to migrate 500 Playwright tests in five business days—with human review taking only hours—they launched their UI redesign 30% faster (Source: How Engagement Agents migrated 500 tests in a week and ...).
The root cause of slow frontend releases isn't a lack of test-writing speed. It's selector fragility: coupling your verification layer to volatile DOM structures rather than user intent.
Why Your Test Suite Breaks Before Your App Does
AI-powered frontend E2E testing combines large language models with runtime DOM analysis to generate, execute, and repair browser tests automatically. Instead of hardcoding #submit-btn-v2, the system evaluates visual context, accessibility roles, and surrounding text.
Think of traditional E2E tests like a GPS that only navigates by the exact paint color of street signs; the moment a city repaints a sign, the car stops. AI self-healing testing acts like a human driver who recognizes the intersection even when the sign is moved or repainted.
When a developer changes a button's div wrapper to a section or renames a class, a traditional script throws a TimeoutError. An AI-enabled runner locates the element by its semantic role—such as *Primary Checkout Button*—and updates the locator automatically.
The 57% Reality Check Nobody Mentions
Before you hand your entire QA pipeline to an AI agent, look at the failure rates in controlled evaluations. In a review of Meta's TestGen-LLM, 75% of generated test cases built successfully, only 57% passed reliably, and just 25% increased code coverage (Source: e2e-skills/docs/llm-generated-e2e-test-evidence.md at main ...).
Similarly, the AutoE2E system achieved 79% average feature coverage, but researchers noted this measured exercised functionality rather than semantic fault-detection accuracy (Source: e2e-skills/docs/llm-generated-e2e-test-evidence.md at main ...). Even strong generative pipelines like GenIA-E2ETest—which reached 82% execution precision and 85% execution recall—still required an average 10% manual-modification rate (Source: GenIA-E2ETest: A Generative AI-Based Approach for End-to-End ...).
The takeaway is clear: blind AI generation creates noisy, unreliable suites. You still need a structured human-in-the-loop workflow.
The G.A.T.E. Framework for AI-Powered E2E
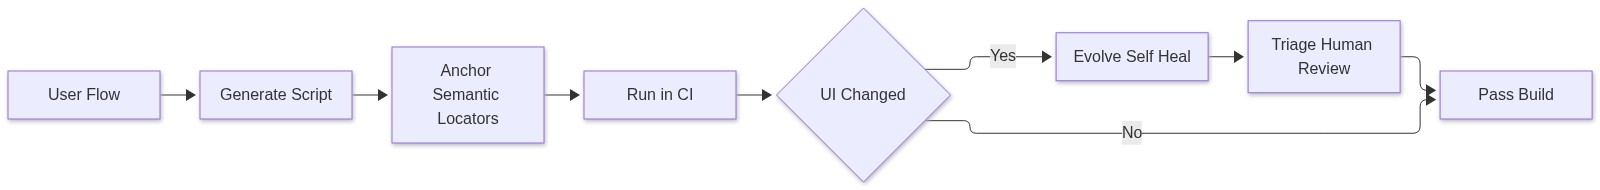
To capture AI speed without drowning in flaky tests, apply the G.A.T.E. system:
- Generate: Feed user flows and staging URLs into an AI test generator to scaffold baseline Playwright or Cypress scripts.
- Anchor: Replace fragile CSS/XPath selectors with semantic anchors (ARIA roles, test IDs, and visible labels).
- Triage: Run generated suites in CI and review the 10% edge-case failures manually (Source: GenIA-E2ETest: A Generative AI-Based Approach for End-to-End ...) to separate real bugs from hallucinated assertions.
- Evolve: Enable self-healing in runtime so minor UI shifts auto-patch without breaking the build.
Worked example: For a checkout flow, you record the happy path once. Generate drafts the cart-to-payment script. Anchor locks onto role=button[name='Pay Now']. When marketing changes the button text to Complete Order, Evolve heals the locator and logs a diff for Triage.
Self-Healing vs. Pure Generation: Which Wins?
If you have to choose where to invest first, prioritize hybrid self-healing with targeted AI generation over pure prompt-to-test tools.
Pure generation without runtime healing simply produces brittle code faster. By contrast, pairing AI generation with self-healing directly attacks maintenance overhead—the #1 reason frontend teams abandon E2E suites. Stellic proved this by using AI-generated and self-healing frontend E2E tests to cut manual testing time by 40% (Source: How Stellic cut manual testing by 40% with Checksum’s AI-powered E2E testing | Checksum).
Start small: apply the G.A.T.E. framework to your top five revenue-critical user journeys (login, signup, checkout, search, settings). Keep human engineers as the final gatekeepers for assertions, and let AI handle the repetitive selector maintenance.
Ship Fearlessly While Others Fix Selectors
Testing was never meant to be a tax on your engineering velocity. Every hour your team spends chasing broken CSS selectors in a CI log is an hour stolen from building features your users actually care about.
When you shift from brittle, DOM-coupled scripts to semantic, self-healing AI workflows, QA stops being the department of no and becomes the safety net that lets you deploy on Friday afternoons without flinching. Master the tools, keep humans in the loop for judgment, and turn your test suite into a competitive advantage.
Sources: How Stellic cut manual testing by 40% with Checksum’s AI-powered E2E testing | Checksum | e2e-skills/docs/llm-generated-e2e-test-evidence.md at main ... | GenIA-E2ETest: A Generative AI-Based Approach for End-to-End ... | How Engagement Agents migrated 500 tests in a week and ...
No comments:
Post a Comment